
Efficient Large Multi-modal Models via Visual Context Compression
Abstract
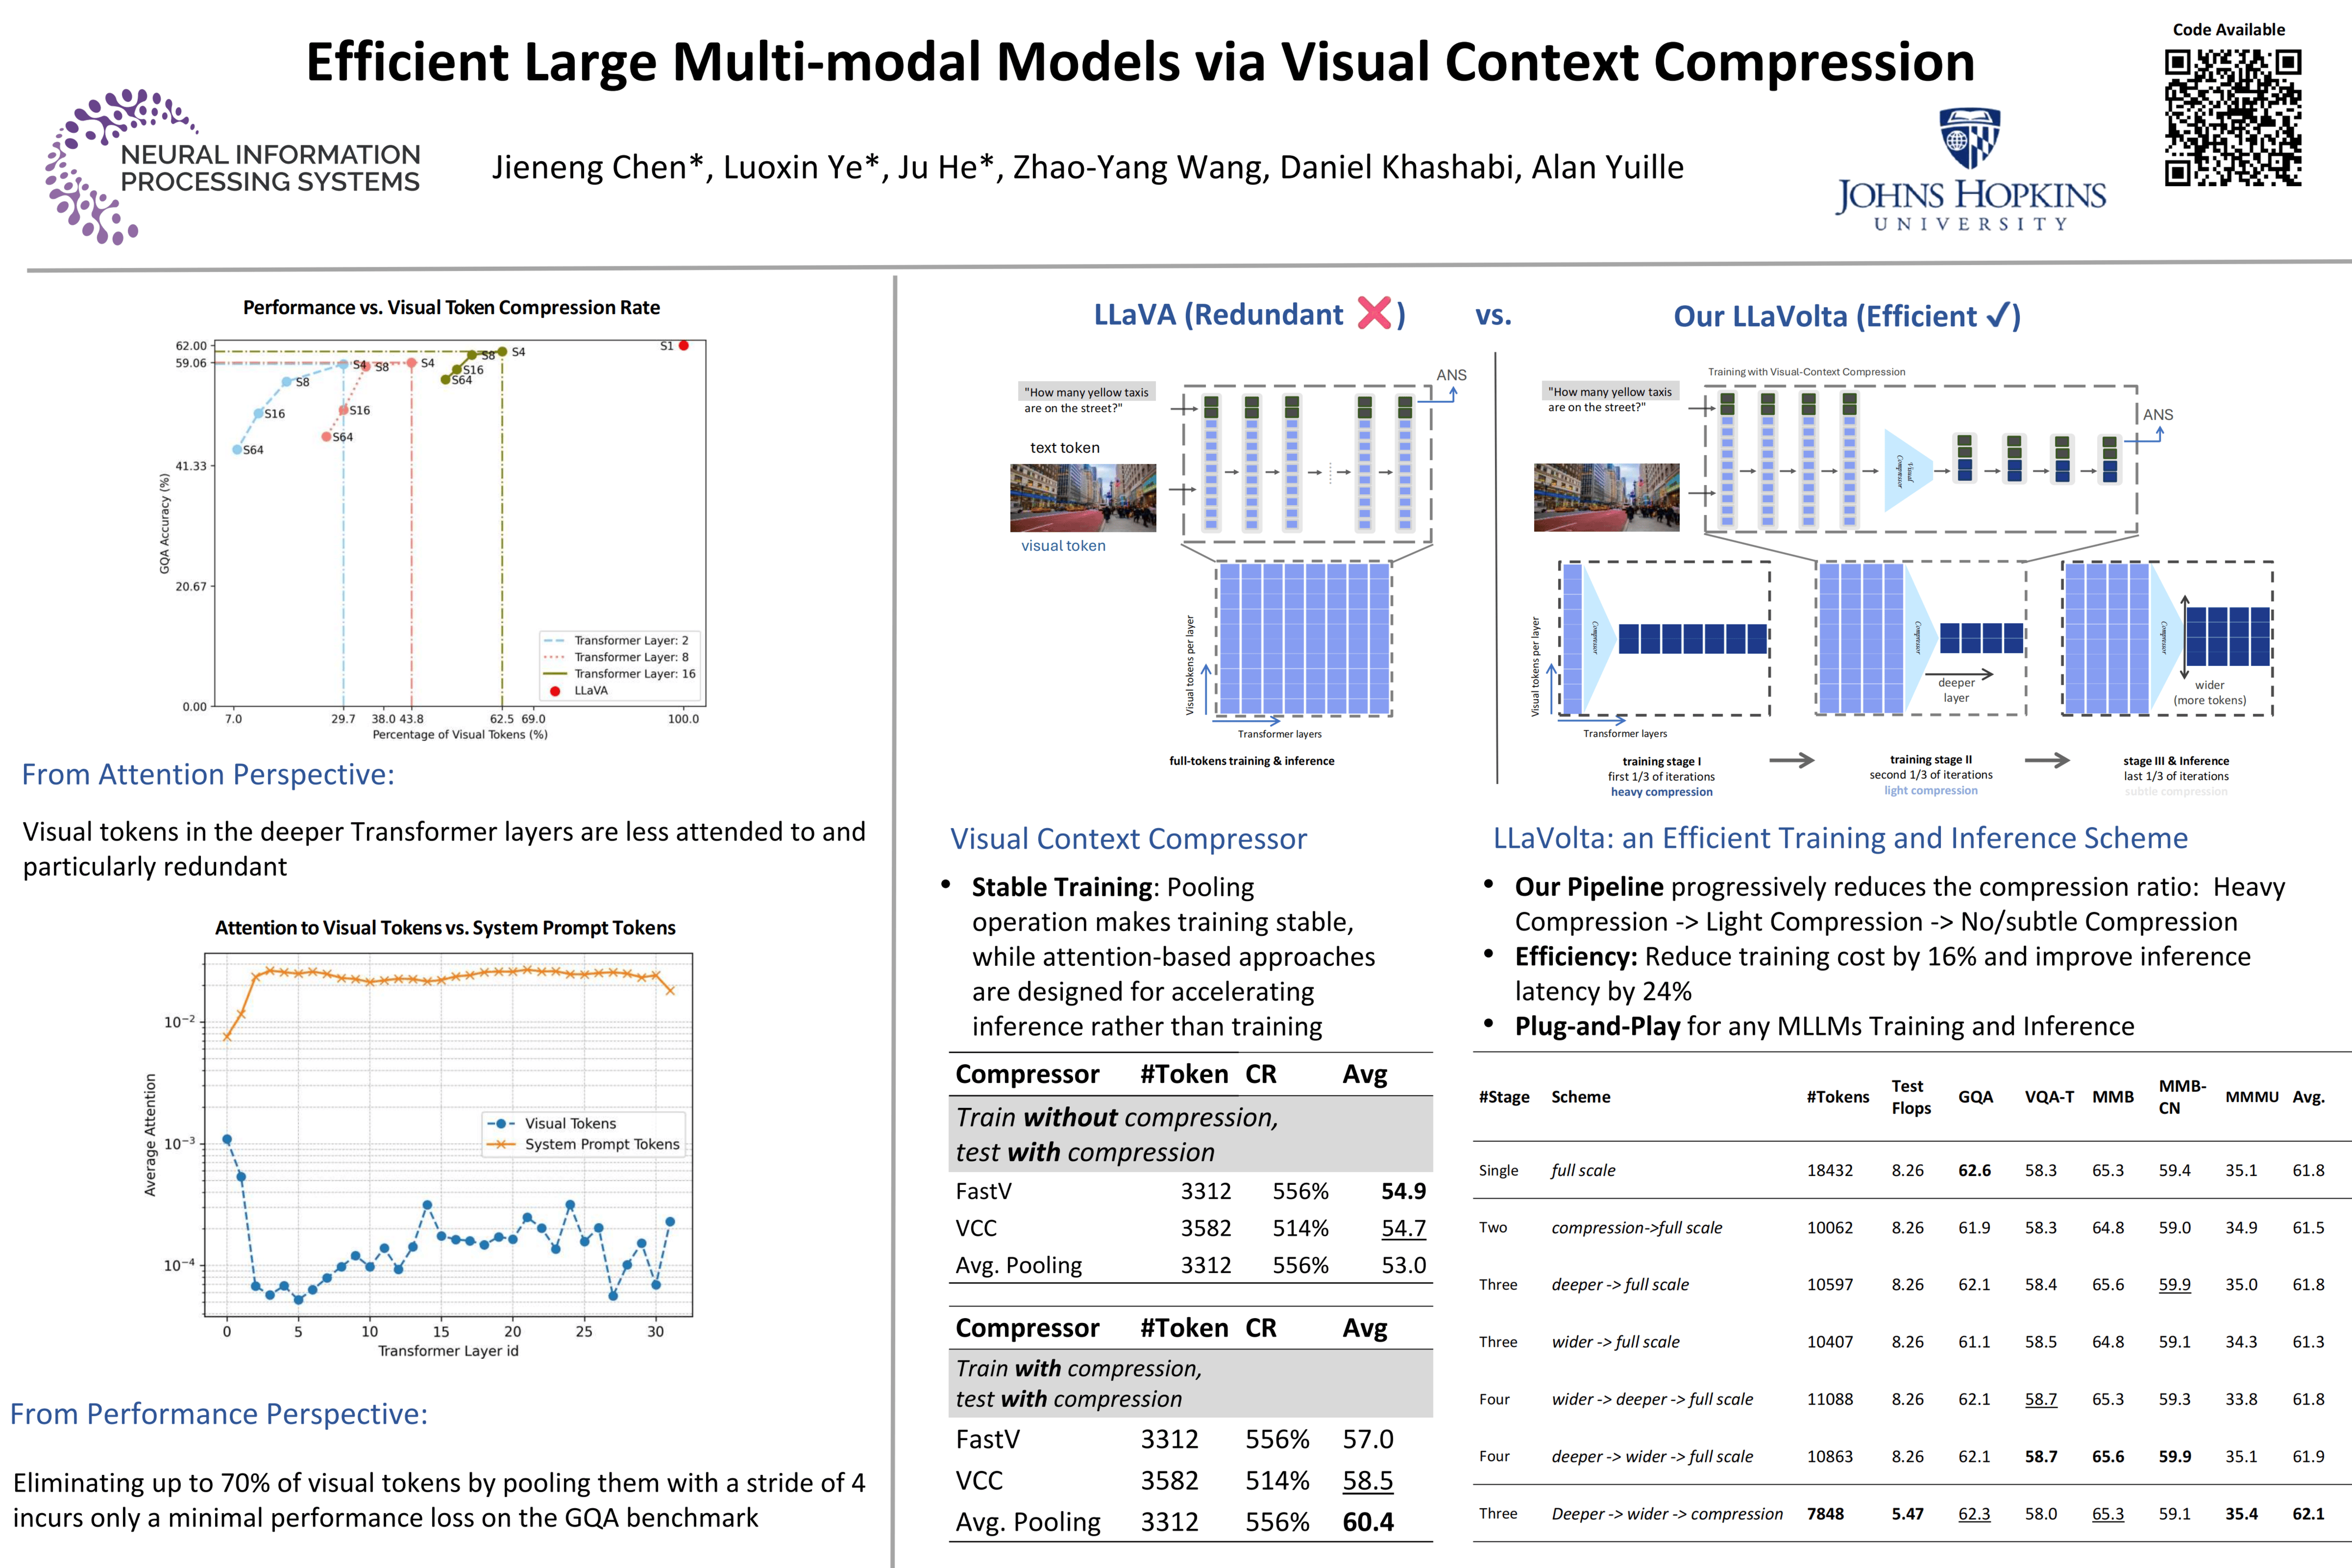
While significant advancements have been made in compressed representations for text embeddings in large language models (LLMs), the compression of visual tokens in multi-modal LLMs (MLLMs) has remained a largely overlooked area. In this work, we present the study on the analysis of redundancy concerning visual tokens and efficient training within these models. Our initial experimentsshow that eliminating up to 70% of visual tokens at the testing stage by simply average pooling only leads to a minimal 3% reduction in visual question answering accuracy on the GQA benchmark, indicating significant redundancy in visual context. Addressing this, we introduce Visual Context Compressor, which reduces the number of visual tokens to enhance training and inference efficiency without sacrificing performance. To minimize information loss caused by the compression on visual tokens while maintaining training efficiency, we develop LLaVolta as a light and staged training scheme that incorporates stage-wise visual context compression to progressively compress the visual tokens from heavily to lightly compression during training, yielding no loss of information when testing. Extensive experiments demonstrate that our approach enhances the performance of MLLMs in both image-language and video-language understanding, while also significantly cutting training costs and improving inference efficiency.